Due to changing conditions in the market for current DDR4/ DDR5 RAM and availability,we accept messages for special CPU, RAM, HD configurations and price inquiries - thanks- 04/03/2026 -Justin Truong
RUN YOUR LLM Models Locally through CPU Instead of GPU's without massive Power Consumption.
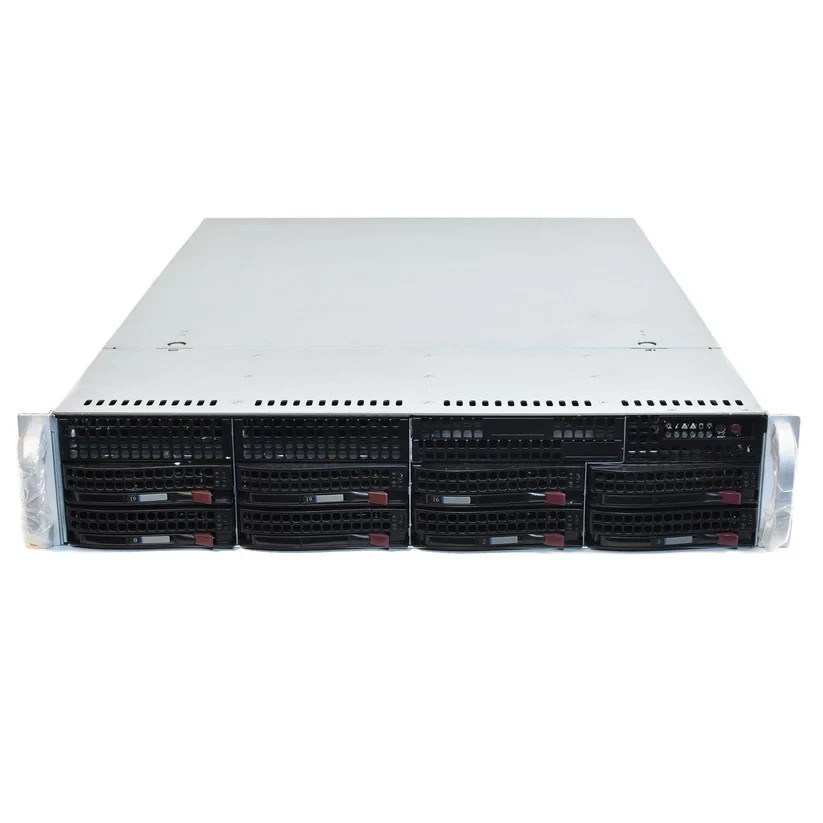
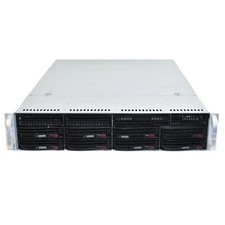
Great Compact Rackmount Server for CPU AI Inference and or Cloud Computing.This Server packs great inference Compute with an astounding Single AMD Epyc Genoa 9654- 96 Core CPU, and high Bandwidth DDR5 RAM
Excellent CPU's for LLM Inference.Llama 2-7B - 13BQuantized models:such as Q4_K_M or Q8Deepseek V3 or R1 etc.QWEN 2.7 72B (GGUF)QWEN 3.5 35B-A3BDeepseek-R1 (Distill 70B or full 671B)Llama 3.3 70BMistral Small 24B
This can be used as a CPU Based LLM system, but this may also used Low Profile Graphics Cards in the PCI-E 5.0 X16 slots.
Please message if you are looking to purchase QTYPlease ask about our 1 Year Warranty optionPlease message for adding shipping insurance (highly recommended)
Build ID: 79300Author: JT 2026-04-03 10:34:13Custom Label (SKU): 79300-A-2U-H13SSL-NT-8LFF-1PSNotes: Installed Ubunutu 22.04LTS
Configuration Specs:CPU: Single AMD Epyc Genoa 9654 - 96 Cores 2.4Ghz Zen4 192 threads 360WMemory: 384GB DDR5 RAM KIT (12x 32GB DDR5)Hard Drives:- QTY 2x 4TB M.2 NVME Drives- QTY 1x ST4000NM000A NEW 4TB SATA Hard Drive or comparable Drive for StorageControllers:- (QTY 4x 40GB QSFP Network Ports) Via 2x Dual 40GB QSFP - Mellanox PCI-E Cards CX314A Installed in the PCI-E Gen5 X8 slotsOnBoard NIC:Dual 10GB-T Ethernet LAN with Broadcom BCM57416 10GBase-T portsOnboard Dedicated IPMI BMC Port
Secondary Chassis/ Motherboard specs:Server Chassis/Case: CSE-825TQ-600LPB 2U 8x LFF Bay Rackmount single PSUMotherboard H13SSL-NTInternal SKU: A-2U-H13SSL-NT-8LFF-1PSMotherboard: H13SSL-NTBackplane: BPN-SAS3-825TQChassis PCI slots: QTY 3x PCI-E Gen 5.0 x16 LP | and QTY 2x PCI-E Gen 5.0 x8 LPMotherboard PCI slots: SlotFront Bays: 8x 3.5" Drive Bays LFFCaddies Included: 8x 3.5" Caddies for SATA DrivesRear Bays: NonePSU Slots: Single PSU SlotPower: 1x 600W Power SupplyMounting: Rail-2U-3U-SM-Yellow-RevBWarranty: Standard
Use Cases per search:Why the EPYC 9654 is Good for Inference:High Throughput: The 9654 delivers significant AI inference performance gains on DLRM (up to ~4.24x) and Stable Diffusion (up to ~5.37x) compared to previous generations, using the AMD ZenDNN library.Large Model Handling: Due to its 12 memory channels and support for up to 6TB of DDR5-4800 RAM, it excels at holding large models and data, often outperforming GPU setups on massive models that exceed VRAM capacity.Model Performance: In tests, a 2P (dual-socket) EPYC 9654 system has shown significant, faster inference for Llama 2 and Llama 3 (7B and 13B) compared to 5th Gen Intel Xeon processors.Versatility: It serves as a strong "traffic cop" in data centers, not just for raw inference, but also for essential preprocessing tasks.
Best Use Cases:Enterprise Large Language Models (LLMs): It provides competitive throughput for models like Llama2-7B and 13B.Recommendation Engines: High performance for DLRM models.Image Generation/Video Processing: Efficient for Stable Diffusion and similar tasks.
Considerations:Optimal Performance: While it has 96 cores, some users suggest that for specific models (like llama.cpp), performance might not scale linearly beyond 64 cores, suggesting that optimized software is key.CPU vs. GPU: While it is powerful, it is generally used for inference where large memory capacity is required (as a lower-cost alternative to massive VRAM setups) rather than for raw, real-time speed in smaller models, where a top-tier GPU might still be faster.Key Reasons the AMD EPYC 9654 is Good for Qwen/DeepSeek:Memory Bandwidth & Channels: The EPYC 9654 supports 12 channels of DDR5-4800, providing the high-speed data transfer needed for CPU-only inference, often exceeding the token-per-second performance of lower-end GPUs when running large models.Massive Core Count: With 96 cores and 192 threads, it can handle highly parallelized inference workloads, which is particularly beneficial for managing large mixture-of-experts (MoE) models like DeepSeek-V3 or R1.Large Memory Capacity: It allows for massive DDR5 RAM installations (up to 6TB), making it possible to run large Qwen or DeepSeek models entirely in system RAM that would otherwise require multi-GPU setups.
Performance Considerations:Inference Speed: While strong for a CPU, it is not faster than top-tier GPUs (like H100s or MI300X). However, it is a highly viable alternative for running 671B MoE models at speeds that allow for practical, albeit slow, interaction.Optimization: Using optimized backend loaders such as llama.cpp with CPU optimizations (GGML) is crucial for getting the best tokens-per-second.
In summary, for a CPU-driven AI workspace that needs to run large Qwen or DeepSeek models (671B, etc.) without relying on high-end GPUs, the 9654 is one of the best choices available.
Warranty Includes 30 Days Standard Warranty covers hardware for the duration stated Expert Pre-sales consulting. With our expertise we will help you find the best solutions for your needs.Expert Post sales Technical Support and consulting - We Set you up for Success
Standard Warranty and Terms of Sale- Standard 30 day limited warranty. - Item tested to power on and all specs show in BIOS, We Warranty Hardware Only, not Software. - Processing times estimated 3 Days. Tracking number will be emailed after Shipped. - 30 Day Hardware parts Warranty. problems must be reported 30 days of when the item is delivered. - Buyer Pays for all shipping, even on returns. (shipping is non-refundable) - Restocking fee as described in the terms of the listing/ order. 20% Restocking fee if not stated. - If you have issues please message us with an item number and the issue you are having. - Our customer service representatives will assist you on getting your problem solved
Message Us- Please have item number ready when contacting, we will try to answer the questions within 24 hours.